 Login for Polarin
The one tier of the AI stack nobody has funded
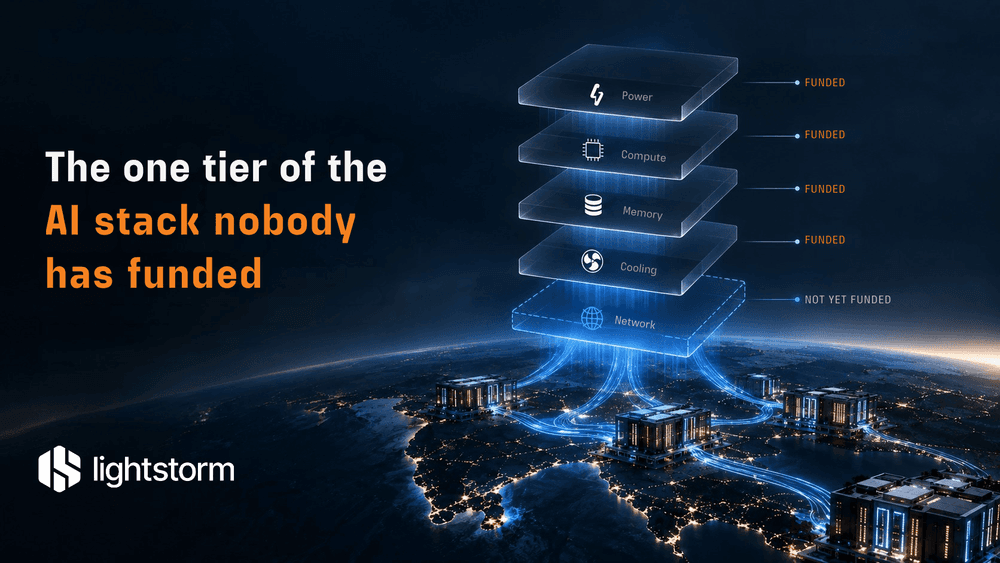
Every layer of AI infrastructure has a gap. Power, compute, memory and cooling get the headlines and the capital. The network between data centres gets neither — and the numbers say it is the layer falling furthest behind.
At the AI Infra Summit in Santa Clara this September, Lightstorm and Nokia put a piece of work on stage that we have been building for most of this year: a quantified case that the wide-area network is the one tier of the AI stack the industry has not yet invested in, and a plan to measure exactly when that matters. The analysis behind it is public — a preprint on arXiv (arXiv:2608.14967) that we tested with industry collaborators before publishing. This post is the short version, written for the people who run networks, data centres and GPU fleets.
Every layer has a gap. One of them has no thesis.
Ask anyone in AI infrastructure where the bottlenecks are and you will get a familiar list — power, GPUs, HBM, cooling, land. All real. All also well funded: every one of those constraints has an investment thesis attached to it, and capital is flowing at it.
Now trace the path a byte takes between two GPUs in different cities: accelerator, HBM, NVLink inside the rack, the scale-out fabric inside the building, the wide-area network to the next site, storage. The industry has spent heavily on every hop in that chain — HBM stacks, NVLink and NVSwitch, 400G and 800G scale-out fabrics — except one. The link between data centres still runs on infrastructure that was sized for pre-AI traffic, and it is the only tier in the continuum without an investment thesis of its own.
The number that shows it
To compare tiers that have nothing in common — memory buses, switch fabrics, long-haul fibre — we use one metric: the bytes of bandwidth a tier can deliver to a GPU per FLOP of that GPU’s compute. We call it the compute interconnect ratio, or CIR, and report it in millibytes per FLOP. For an H100 at 989 TFLOPS dense BF16 the ladder looks like this: HBM sits at 3.39 mB/F, NVLink at 0.910, scale-out InfiniBand between 0.006 and 0.050, and a conventional shared WAN — 1 to 10 Gbps per eight-GPU node — lands somewhere between 0.0000158 and 0.000158. Four to five orders of magnitude, top to bottom.
The gap is also widening. GPU compute has grown about 48% a year on a dense basis from the A100 in 2020 to the B200 in 2025, while network capacity at every tier has grown 25–32% a year — so the bandwidth available per FLOP beyond the package falls 11–16% a year, and the compute-to-bandwidth gap widens 12–19% a year.
The shape of it is what I find most telling. On a consistent dense basis the B200 generation actually holds on-package CIR roughly flat — HBM at about 3.56 mB/F against the H100’s 3.39 — and lets NVLink slip only modestly. The tiers the industry funded have broadly kept pace with compute; the wide-area tier, which nobody funded, has not. That is what “no investment thesis” looks like when you plot it.
Why inference, not training, forces the question
Training tolerates the WAN — asynchronous gradient exchange between sites needs on the order of 5 Gbps in our model, and the workload can wait — and inference does not. A 70B multi-head-attention model at 4K context carries a 10.7 GB KV cache. Moving that between a prefill site and a decode site inside a 40 ms time-to-first-token budget takes 2,147 Gbps of transfer capacity: roughly 429× the training demand, and 215× a dedicated 10 Gbps link.
I want to be careful with that number, because it is the multi-head-attention bound. Modern attention architectures cut cross-site demand by 8–37×: grouped-query attention at 1/8 KV heads needs about 268 Gbps, latent attention around 58 Gbps. Anyone who leads with the 2,147 figure and stops there is overstating the case.
But the same architectures that shrink the demand also shrink the point at which moving state across sites becomes cheaper than recomputing it. For 70B MHA that crossover sits at 74–111 Gbps per stream; under GQA it drops to 9–14 Gbps, which is a link rate any wide-area service provisions routinely today. Modern attention does not make the network stop mattering. It makes cross-site disaggregation stop being exotic, and it moves the binding constraint from “can one stream cross?” to aggregate capacity and tail behaviour.
Agentic workloads are where the aggregate shows up. A 20-step agent session with growing context, re-transferring its accumulated state on a fraction of its site-hops, moves around 25 GB under GQA; ten such sessions a second is roughly 2 Tbps of sustained cross-site demand — latency-tolerant per step, bandwidth-hungry in aggregate, and bandwidth-bound even at continental distance.
The answer is not “more bandwidth everywhere”
The industry collaborators we tested this with pushed us hardest here, and rightly. More bandwidth helps; the question is whether provisioned bandwidth beats the alternatives — recomputation, KV compression, locality-aware routing, or simply overprovisioning a packet backbone — and the answer is: only in specific regimes.
At list GPU prices, recomputing the prefill is cheaper than transferring it. Transfer wins when GPU scarcity and KV reuse multiply the effective cost of a GPU-second by roughly 5–20× — hot fleets, agentic pipelines, GPU-scarce markets — and modern attention moves that breakeven an order of magnitude in transfer’s favour. Compression is a genuine substitute up to a quality ceiling: 8× KV compression lifts prefill-GPU utilisation on a 10G link from 12% to 52%, but the KV channel carries reasoning capacity, not just latency, and past a point only real bandwidth preserves both.
The packet-versus-optical debate resolves the same way. A well-run IP backbone reallocates traffic in milliseconds, but statistical multiplexing and traffic steering allocate capacity that is already lit; they cannot create it. When aggregate demand between two sites approaches what is lit, queueing takes over regardless of routing intelligence — p99 queue wait runs about 3× the transfer time at 50% utilisation, 7× at 70%, and past 20× at 90%. At that knee there are exactly two remedies, permanent headroom or a change in the amount of lit capacity, and a hyperscaler overprovisioning its backbone three to five times buys the first at hyperscaler capital intensity while everyone else needs the second, triggered before the knee.
There is a second, physical reason the optical layer matters, and it is the one I would ask every network architect to sit with. The transport the AI stack actually prefers is RDMA, and RoCEv2 was designed for lossless fabrics with microsecond feedback loops. At the loss rate of an ordinary shared WAN — one packet in a hundred thousand — a 400G RoCEv2 flow at 56 ms round-trip collapses to about 24% goodput; the pipe stays busy, mostly re-sending. Holding 90% goodput needs paths one to two orders of magnitude cleaner than a shared WAN, with no delay variation that reorders packets. A loss and jitter floor is therefore a bandwidth specification, not a quality garnish — and deterministic delivery at that level exists at layer 1, on dedicated wavelengths, in a way no queueing discipline provides at layer 3 under load.
Put those together and the design that falls out is a two-timescale system: a packet-fronted service interface making per-request decisions in milliseconds, optical elasticity underneath changing lit capacity in seconds to minutes, triggered at the queueing knee, with tails engineered at layer 1. Our published India simulation gives a sense of the stakes: a 70B model at 4K context over 1,000 km moves from 9.75 s time-to-first-token and 12% GPU utilisation on a shared 10G link to 1.38 s and 84% at 400G.
What Lightstorm is doing about it
I will keep this section deliberately short, for reasons anyone in a competitive market will understand.
The analysis makes falsifiable predictions, and predictions are worth nothing until someone measures them on production infrastructure. Lightstorm is building the network half of that measurement. We are assembling a three-site testbed on a new, deep-buried production fibre corridor in India, with open optical line systems from multiple vendors under interoperability test and an SDN-driven optical control plane on top. Polarin, our network-as-a-service platform, is being extended in the direction the paper describes: a control loop in which the inference layer asks for capacity and the optical layer supplies it, on the timescale of provisioning rather than of a request.
Around that testbed we have published a ten-metric measurement plan — provisioning and capacity-step latency, delay-variation percentiles, allocation-loop timing, multi-tenant isolation, the real transfer-versus-recompute flip point, compression-quality curves, and measured cost per gigabit at pilot scale — with each metric tied to a specific prediction in the paper, so each one can prove us wrong.
The pilot window opens in late 2026 and it is open to collaborators, and that is not a courtesy line. An operator can measure what only an operator can measure, but the workload truth — real time-to-first-token, real utilisation, an RDMA-class transport running over actual wavelengths — has to come from the GPU vendors, serving-stack and inference-fabric providers who own those layers. No single company can, or should, assemble this evidence alone.
Where I land
The workloads now arriving — agentic, multi-site, sovereignty-split — are the first that cannot route around the wide-area tier. My guess is that the evidence shows up first in Asia, and specifically in India, where the GPU fleets are hot, the distances between compute and demand are real, and new fibre is going into the ground that can be designed for this traffic rather than retrofitted to it.
One thing I have not resolved in my own head is where the storage tier fits. Checkpointing state to NVMe and reloading it on demand sits somewhere between transfer and recompute, and we have not modelled it yet — the kind of contribution the open plan is meant to absorb.
Two decades ago, Metro Ethernet’s requirements told the market: here is the missing tier, here is how to specify it, here is the evidence. That is what this work is for.
The full analysis, reproducible model and measurement plan: arXiv:2608.14967 — “When Does Distributed AI Inference Need More Wide-Area Bandwidth? A Co-Design Evaluation of Optical, Packet, and Software Levers” (Prasanna C, Lightstorm, August 2026). To discuss participation in the late-2026 pilot window, contact Lightstorm.
Prasanna C
Chief Product Officer